
How to Use an AI Agent for SEO Content Creation Without Losing the Facts

An AI agent for SEO content creation researches a topic across live pages, builds an outline, drafts the article and can revise or publish it, so the real decision is which of those jobs you let it run unsupervised. Our answer: hand it the outline and the draft, but never the facts. The prose is the easy part for a model. What decides whether the page is worth ranking or quoting is the data underneath, and that belongs in a sheet you own, with a source next to every row.
Table of Contents
- What an AI Content Agent Does for SEO
- Research, Outline, Draft: The Loop Behind the Output
- Running the Workflow From a Source Sheet
- Criteria That Separate a Useful Agent From a Text Generator
- Mistakes That Make Agent-Written Pages Thin
- When an Agent Is the Right Call, and When It Isn't
- How BrowseWiz Fits the Research Half
- Frequently Asked Questions
What an AI Content Agent Does for SEO
An AI content agent is a language model given tools (a browser, search, files, sometimes a CMS login) and a goal, so it can gather sources, plan, draft and revise a page in a loop instead of answering a single prompt. That loop separates it from a chat assistant, which writes from whatever you paste in, and from an SEO platform, which scores keywords and gaps but leaves the reading to you. It serves the person who would otherwise spend the opening stretch of every article collecting competitor headings, product specs, prices and dates into a doc. The catch sits in the first stage: the content outline an SEO AI agent produces is a summary of the pages it happened to read, so if those pages were stale, paywalled or misread, every heading inherits the error, and nothing in the finished prose tells you which claim came from where.
Research, Outline, Draft: The Loop Behind the Output
Under the hood the agent runs a plan, act, observe cycle. It breaks your brief into sub-tasks, opens pages, reads the rendered text, decides whether it has enough, and opens more. Then it compresses what it read into working notes.
The draft is written from those notes, not from the pages. That compression is the step you never see, and it is where an exact price becomes "around" a price, a spec from one model attaches to its sibling, and a date from an archived page becomes current. Longer research runs make it worse, because more notes compete for the same context.
Whether a model wrote the words is not what ranking turns on. Ahrefs measured a correlation of just 0.011 between the share of AI-generated content on a page and its Google ranking position, and concluded that Google neither significantly rewards nor penalizes AI content. The line is drawn elsewhere.
So which AI agents can write and publish AEO-optimized content, meaning pages built to be quoted by answer engines? Almost any capable one can produce the shape: a direct answer first, tight definitions, question headings, a clean summary table. Publishing is one more form to fill. What no agent produces from reading page one is a fact the answer engine has not already seen ten times. That has to come from a source you collected and checked.
Running the Workflow From a Source Sheet
- List the facts the article will stand on before any prose exists: the products or items, the prices, specs, dates and terms, and the sites that hold each one.
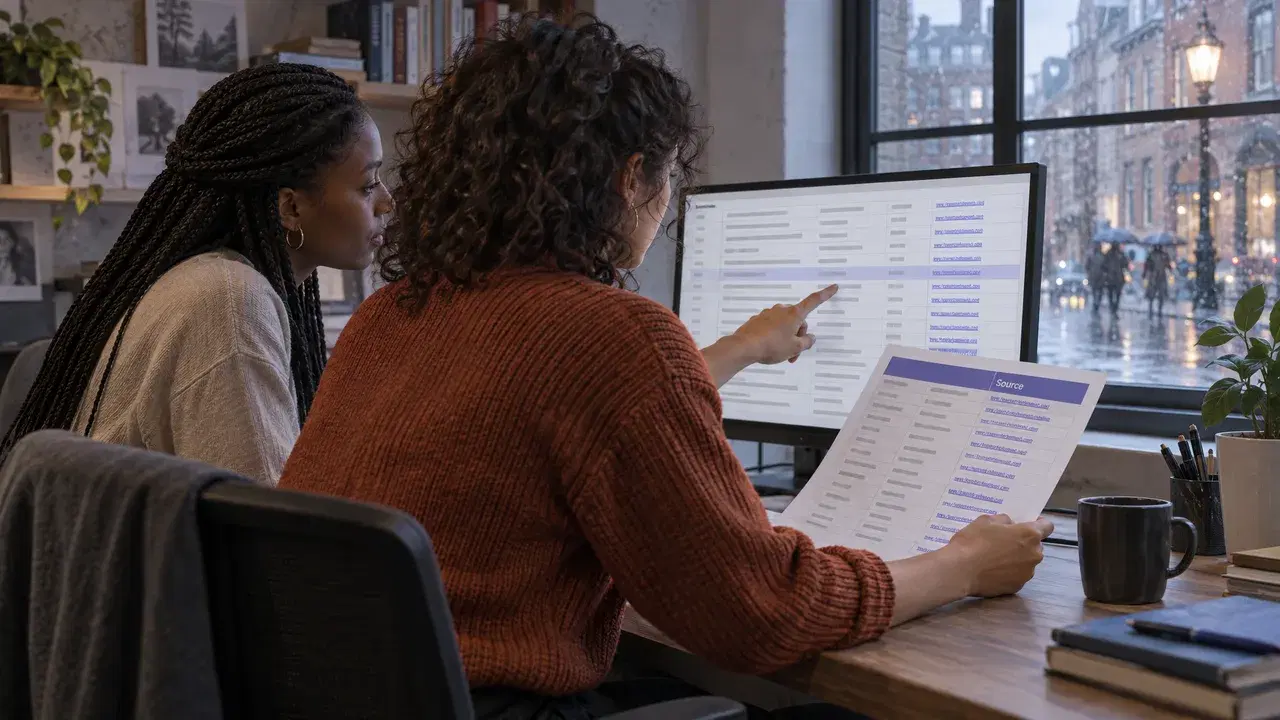
- Collect those facts into a Google Sheet with one row per item and a column recording the source URL for every row, using a browser agent that reads the rendered page rather than raw HTML.
- Open a sample of rows against their source pages and fix anything the extraction misread, before the drafting agent sees the sheet.
- Give the drafting agent the sheet as its only allowed source for numbers and named specifics, and let it browse freely for context, terminology and how competing pages are structured.
- Ask for the outline first and hold every heading against the sheet; cut any heading that has no rows behind it, because that is where the model will invent.
- Draft, then edit with a person who checks every figure in the text against its row.
- Schedule the sheet to refresh, and revise the published page when a value it cites changes.
Step six is normal practice. Whatever the exact share in your workflow, the edit pass is where the sheet earns its keep: an editor checking twelve figures against twelve rows takes minutes, while an editor checking twelve figures against "the agent read some pages" has to redo the research.
Criteria That Separate a Useful Agent From a Text Generator
Polish of the prose is the wrong test; every current model writes fluent paragraphs. Check these instead:
- Source traceability. Look at the output, not the marketing: does each fact or row carry the URL it came from, so an editor can open it in one click?
- Rendered and signed-in pages. Point it at a page that loads prices with scripts or sits behind your login, and see whether it gets the data without asking you to export cookies or hand over a password.
- Repeatability. Run the same research a week later and see whether it updates the existing rows and shows the old values, or produces a fresh, unrelated list.
- Approval before actions. Ask it to submit a form or press publish and confirm it stops and asks first.
- Model choice. Check whether you can pick or swap the model, since drafting quality and cost shift between releases.
Traceability matters more once answer engines stand between your page and the reader. Pew Research Center found that about six-in-ten respondents (58%) ran at least one Google search in March 2025 that produced an AI-generated summary. When those users saw an AI summary, they clicked a traditional search result link in 8% of all visits. Some 6% of the sources linked in AI overviews were .gov websites, compared with 2% for standard search results.
Our reading of those numbers: summaries lean toward primary, checkable sources, and a click is rare enough that being the cited source is the realistic goal. A draft that paraphrases what the summary already paraphrased gives it nothing to cite. If you are weighing tools on these criteria, our comparison of scrapers and agents sets them side by side.
Mistakes That Make Agent-Written Pages Thin
Letting one agent research and write in a single pass is the default setup, and it hides errors by design. The model reads, compresses and drafts in one context, so a misread spec looks exactly like a correct one in the output. Split the jobs. Research lands in rows you can inspect; drafting reads only those rows.
Copying the headings of the top results is a second trap, because the agent's outline then becomes the average of page one. You get a page that covers what everyone covers in the order they cover it, which is precisely the "no added value" pattern Google's guidance describes. Start the outline from what your sheet holds that competing pages do not.
A one-off snapshot is another quiet failure. Prices, availability, plan names and dates drift after you publish, and the page keeps asserting the old value with full confidence. Spreadsheet formulas can pull some page data, but the limits of IMPORTXML show up fast on modern pages. Tie the article to a sheet that refreshes on a schedule.
Granting the agent unattended publish rights turns every mistake into a live page. An agent that clicks "publish" on its own will also publish its hallucinated table. Keep a human approval on the final action, even when the drafts have been clean for weeks.
Uploading session cookies or passwords to a hosted service so it can reach logged-in data is the trade many teams make without noticing. Supplier portals, analytics dashboards and member-only listings often hold the best facts for a page. Read them in your own signed-in browser instead of shipping your sessions to someone else's server.
When an Agent Is the Right Call, and When It Isn't
Use an agent if your pages stand on facts that live on websites and change: product roundups, price comparisons, listings, spec pages, local directories, release trackers. Here the research is most of the work, the facts can be checked row by row, and a refreshing sheet keeps the published page honest. You get speed without giving up accuracy, as long as the sheet comes first.
Skip it, or limit it to formatting help, if the value of the page is your own experience, a strong opinion or original reporting. An agent can tidy your notes into a clean structure, but it has nothing to add, and research from page one will pull your piece toward what everyone else already said.
If you sit in between, start with research only. Let an agent fill the sheet for one article, check it, and write the piece yourself. If you want to see how an agent behaves on live pages before trusting it with that, read through the BrowseWiz documentation for the browser agent. Once the sheet proves reliable across a few articles, hand over the drafting too.
How BrowseWiz Fits the Research Half
BrowseWiz covers the data side of this workflow and leaves the writing to whichever agent or editor you prefer. You describe the rows in plain words, and there are no selectors or scrapers to build or fix. It reads sites you're signed into in your own Chrome, with no cookie or password upload. The rows land in a new Google Sheet in your Drive with a Source column per row, which is the traceability a draft needs.
Nothing depends on selectors or recorded clicks, so a redesigned page doesn't break the research. One plain-language message can cover several sites instead of a robot per site. Scheduled refreshes update rows in place and keep the old value. Previous values sit in their own column beside the refreshed ones, so you can see which facts behind a published article have moved.
For drafting next to the data, the side-panel chat works over pages, PDFs and images, and Promptbook saves prompts with fill-in variables. When a task needs clicks, the agent clicks and types to fill forms and carts, stopping to ask before final actions. You can skip asking on trusted sites or for an approved plan.
The limits are worth knowing before you commit. Chrome has to be open: scheduled refreshes and monitors run only while the browser is open. If a site signs you out, you sign in again in Chrome. The Free plan includes one daily scheduled task and one monitor. To set up a research sheet for your content, talk to us, or compare the Free, Pro and Max plans.
Frequently Asked Questions
Can an AI agent do my SEO for my website?
It can do the repeatable parts: collecting facts from competing and source pages, drafting outlines, writing first drafts, filling metadata and keeping figures current. It cannot decide which topics your site has standing to cover, and it cannot supply the experience or judgment that makes a page worth citing. Treat it as a research assistant and a fast first-draft writer. Strategy, topic choice, the final edit and the publish button stay with you, because those are the steps where a confident wrong answer does real damage.
How often should the facts behind a published article be refreshed?
Match the refresh to how fast the source changes: prices and stock daily or weekly, specs and plan names monthly. In BrowseWiz, scheduled sheet updates run up to once a day, at the time you set. When a cited value moves, update the article that same week, so the published page never contradicts its own source.
Which AI model should handle the drafting?
Pick the model you write best with, and keep the choice swappable, because drafting quality changes with each release while your research sheet stays the same. BrowseWiz lets you choose the model with your own API key or an OpenAI-compatible endpoint, and custom tools and MCP servers can be connected. It also integrates with Claude Code. Our overview of AI models covers the current options. Since numbers come from the sheet, a model swap changes the style of the draft, not its facts.
About Tom
I'm a software engineer and solutions architect specializing in AI-driven tools and productivity software, passionate about helping users reclaim their valuable time through intelligent automation.